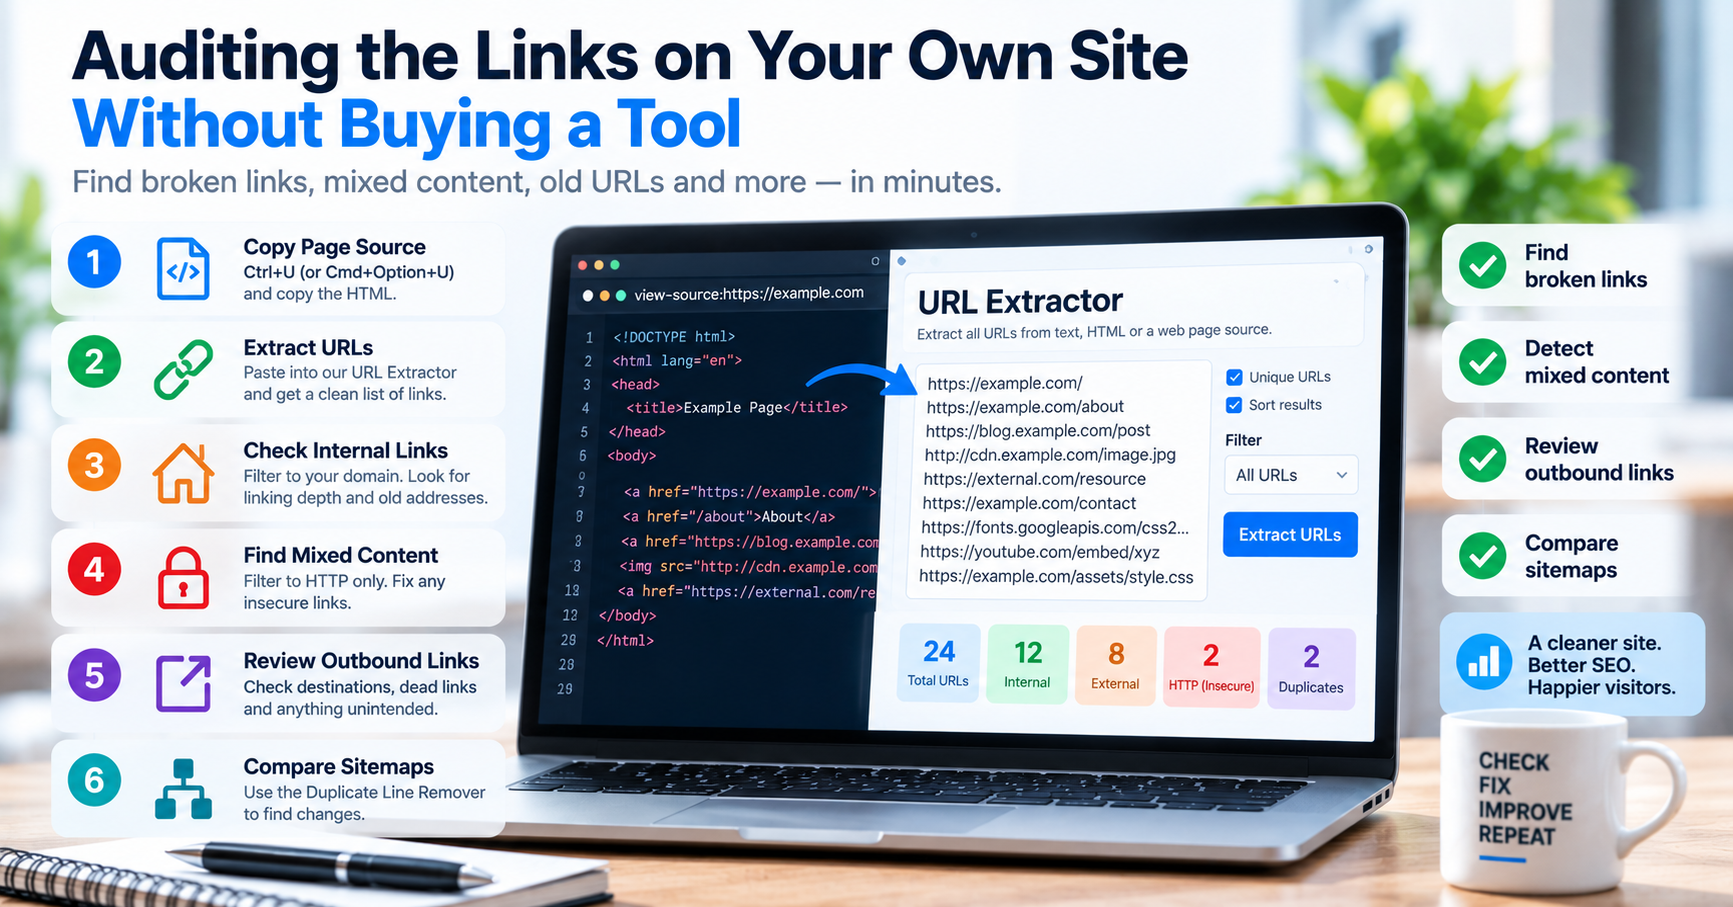
Hyperlinks are the fundamental connective fabric of the World Wide Web. Search engine crawlers navigate the internet by traversing links from document to document, using link architecture to discover new content, evaluate topical hierarchy, and distribute PageRank authority across domain subpages. For human visitors, links represent the primary navigation pathway through your content and commercial conversion funnels.
Yet, internal link decay is an inevitable byproduct of continuous website evolution. URL structures get refactored, outdated products are unpublished, third-party reference domains expire, and content editors mistype destination slugs. Left unchecked, broken links (404 errors), recursive redirect loops, and orphaned pages quietly erode your search engine rankings and increase user bounce rates.
The Four Critical Internal Link Failures
| Issue Category | Technical Mechanism | Search Engine & User Impact |
|---|---|---|
| Dead Links (404 Not Found) | Link points to an endpoint returning an HTTP 404 or 410 Gone status. | Dead ends crawler navigation; wastes crawl budget; degrades user trust. |
| Redirect Chains & Loops | Link hops through multiple 301/302 redirects (e.g., A → B → C). | Adds round-trip latency to page loads; dilutes PageRank; crawlers abandon after 5 hops. |
| Orphan Pages | Valid pages that receive zero internal links from anywhere on the site. | Invisible to search bots unless listed in XML sitemaps; struggle to rank. |
| Mixed Protocol Links | Linking internally to insecure http:// endpoints on an HTTPS site. |
Triggers unnecessary protocol redirects; potential mixed content warnings. |
Building an Automated Internal Link Crawler in Python
While commercial desktop crawlers exist, you can build a lightweight, targeted link auditor in Python to scan your site, detect broken links, and measure HTTP response codes:
import requests
from bs4 import BeautifulSoup
from urllib.parse import urljoin, urlparse

def audit_internal_links(base_url: str, max_pages: int = 50):
    domain = urlparse(base_url).netloc
    visited = set()
    to_visit = [base_url]
    broken_links = []

    while to_visit and len(visited) < max_pages:
        current_url = to_visit.pop(0)
        if current_url in visited:
            continue
        visited.add(current_url)

        try:
            res = requests.get(current_url, timeout=5)
            if res.status_code >= 400:
                broken_links.append((current_url, res.status_code))
                continue

            soup = BeautifulSoup(res.text, 'html.parser')
            for a_tag in soup.find_all('a', href=True):
                href = a_tag['href']
                full_url = urljoin(current_url, href)
                # Keep audit within domain
                if urlparse(full_url).netloc == domain and full_url not in visited:
                    to_visit.append(full_url)
        except Exception as e:
            broken_links.append((current_url, str(e)))

    print(f"Audit Complete. Scanned {len(visited)} pages.")
    print("Broken Links Detected:", broken_links)
Command-Line Rapid Probing with cURL
To inspect HTTP headers and redirect status codes directly from your terminal, use curl -I:
# Follow redirects and print HTTP status transitions
curl -ILs -o /dev/null -w "%{http_code} | Total Redirects: %{num_redirects}\n" https://tuwebtools.com/tools
Internal Linking Optimization Strategies
- Flatten Your Click Depth: Ensure every important article or tool is reachable within a maximum of 3 clicks from your homepage.
- Use Descriptive Anchor Text: Avoid generic phrases like "click here" or "read more". Incorporate keyword-rich anchor text that conveys the destination's topical focus (e.g., our text separator utility).
- Clean Out Redirects at the Source: When updating a URL slug, update all existing internal hyperlinks across your database so they point directly to the new 200 OK canonical address.