In distributed computing, web engineering, and email systems, data must frequently travel across network protocols that were originally architected exclusively for 7-bit ASCII text transmission. When raw binary streams—such as cryptographic signatures, compiled byte code, or compressed image data—pass through legacy gateways, specific control characters (such as line feeds, carriage returns, or null bytes) can be silently modified, truncated, or dropped, resulting in irrecoverable data corruption.
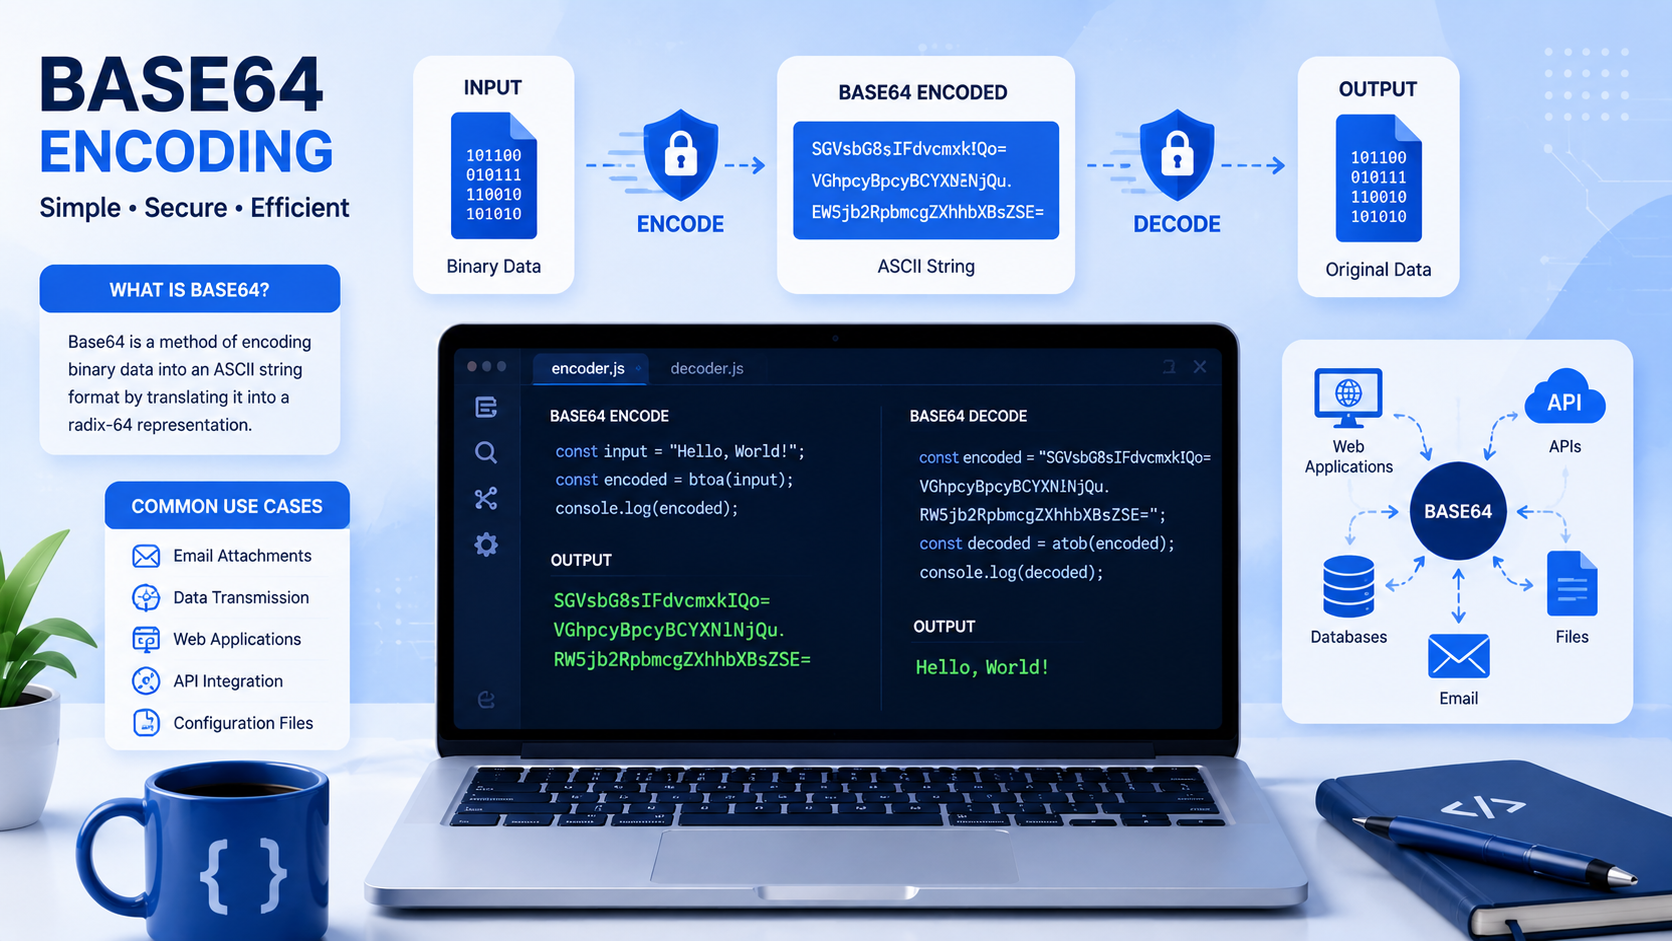
To solve this transmission challenge, computer scientists developed Base64 encoding (formalized in RFC 4648). Base64 converts arbitrary binary bytes into an unambiguous printable alphabet consisting of 64 standardized ASCII characters. However, developers frequently misunderstand its operational purpose, confusing encoding with encryption or misjudging its substantial 33% bandwidth overhead.
The Mathematical Mechanics: How 8-Bit Bytes Become 6-Bit Radix Characters
Standard computing represents digital data in 8-bit octets (bytes), yielding $2^8 = 256$ possible byte values per unit. Base64 represents data in 6-bit radix units, yielding $2^6 = 64$ possible character values. Because the least common multiple of 8 and 6 is 24, the Base64 transformation algorithm processes data in chunks of 3 bytes (24 bits) and outputs 4 Base64 characters (24 bits):
| Step | Byte 1 ('M') | Byte 2 ('a') | Byte 3 ('n') |
|---|---|---|---|
| ASCII Text | M |
a |
n |
| Hex Value | 0x4D |
0x61 |
0x6E |
| 8-Bit Binary | 01001101 |
01100001 |
01101110 |
| Combined 24-Bit Stream | 010011010110000101101110 |
||
| Split into 6-Bit Chunks | 010011 (19) → T |
010110 (22) → W |
000101 (5) → F | 101110 (46) → u |
| Final Base64 Output | TWFu |
||
Handling Padding with the '=' Sign
What happens when the input stream length is not evenly divisible by 3? The algorithm appends zero bits to complete the final 6-bit unit, and records the padding using one or two = characters:
- If 1 byte is left over (8 bits): The bits are padded with four zeros to create two 6-bit numbers, and two
==padding characters are appended. - If 2 bytes are left over (16 bits): The bits are padded with two zeros to create three 6-bit numbers, and one
=padding character is appended.
The 33.3% Payload Overhead Penalty
Every software architect must recognize that Base64 introduces an unavoidable 33.3% payload size expansion. Because 3 bytes (24 bits) expand into 4 characters (32 bits), the bandwidth and memory ratio is:
$$\text{Expansion Ratio} = \frac{4}{3} \approx 1.3333 \quad (+33.33\%)$$
For example, a 3.0 MB raw image file encoded into Base64 becomes 4.0 MB of ASCII text. When sent over HTTP, this extra megabyte consumes additional network bandwidth, increases mobile radio battery drain, and requires client CPU cycles to decode back to binary.
Standard Base64 vs. URL-Safe Base64 (Base64URL)
The standard Base64 alphabet includes characters + (plus) and / (slash). In web environments, these characters conflict with URL syntax:
- The
+character represents an encoded space in URL query strings. - The
/character denotes a path separator in RESTful URL routes.
RFC 4648 Section 5 defines Base64URL to eliminate this conflict:
Standard Base64:  +  and  /  (with '=' padding)
Base64URL:        -  and  _  (with '=' padding omitted)
Base64URL is the universal encoding standard for JSON Web Tokens (JWT), WebAuthn cryptographic keys, and URL-embedded security parameters.
Production Implementation in Python and JavaScript
Python 3 (Standard vs URL-Safe)
import base64

raw_data = b"TU Web Tools cryptographic payload"

# Standard Base64
std_encoded = base64.b64encode(raw_data).decode('ascii')
print(f"Standard: {std_encoded}")

# URL-Safe Base64 (RFC 4648)
url_encoded = base64.urlsafe_b64encode(raw_data).decode('ascii').rstrip('=')
print(f"URL-Safe: {url_encoded}")
Modern Browser JavaScript (Handling Unicode/UTF-8)
// Native btoa() only accepts binary ASCII strings (code points <= 255)
// To safely encode UTF-8 text containing emoji or international characters:
function utf8ToBase64(str) {
    const bytes = new TextEncoder().encode(str);
    const binString = Array.from(bytes, byte => String.fromCharCode(byte)).join('');
    return btoa(binString);
}

function base64ToUtf8(base64) {
    const binString = atob(base64);
    const bytes = Uint8Array.from(binString, char => char.charCodeAt(0));
    return new TextDecoder().decode(bytes);
}

const encoded = utf8ToBase64("Hello World 🚀 Zero-Knowledge");
console.log(encoded); // Valid UTF-8 Base64 output
Interactive Diagnostic Checklist
- [ ] Remember that Base64 provides zero confidentiality; never use it to "protect" sensitive credentials.
- [ ] Use Base64URL (replacing
+//with-/_) when embedding data in URLs or JWTs. - [ ] Avoid storing large binary files as Base64 strings in relational databases; use dedicated object storage (S3).
- [ ] Use our free browser-based Base64 Encoder & Decoder for zero-upload local inspection.